Google Maps Scraping Without IP Bans: Residential Proxies, Grid Tiling & Anti-Bot Architecture
Master large-scale Google Maps data extraction without IP bans. Learn geographic grid tiling, rotating residential proxy pools, TLS fingerprint spoofing, and legal compliance.
Sikander Ali
Senior Software Architect, TechnoFreaks
Direct Answer: How to Scrape Google Maps Without IP Bans Scraping Google Maps at scale without IP bans requires three core technical components: (1) Geographic coordinate grid tiling to bypass Google's 120-result pagination ceiling, (2) Rotating residential proxy pools configured with 60-second sticky sessions and randomized human request jitter (1.8s–4.2s), and (3) TLS/JA4 fingerprint matching to prevent heuristic bot detection. Platforms like SitePitch automate this complete architecture out of the box.
Key Takeaways (TL;DR)
- The 120-Result Wall: Google Maps never returns more than 120 results per search query. You must tile your target region into geographic bounding boxes to extract 100% of available businesses.
- Datacenter IPs are Dead: Cloud IPs from AWS, OVH, or GCP trigger immediate CAPTCHA blockades. Only peer-to-peer residential and 4G mobile proxies survive high-velocity Google Maps extraction.
- Protocol Fingerprinting: Modern anti-bot engines analyze TCP window sizes, TLS cipher order, and HTTP/2 headers—not just User-Agent strings.
- The Downstream Multiplier: Scraping raw contacts is only half the battle; pairing extraction with automated website gap detection and live interactive demo prototypes yields 10x higher reply rates.
# 1. The Anatomy of a Google Maps IP Ban
Engineers building lead generation scrapers for marketing agencies or sales teams inevitably encounter the same wall within their first 500 requests: HTTP 429 Too Many Requests, followed by unsolvable reCAPTCHA v3 invisible challenges and immediate IP blacklisting.
To build an extraction engine capable of pulling 50,000+ verified B2B leads daily, you must first understand how Google's anti-bot detection pipeline operates.
# The 120-Result Pagination Ceiling
The most common misconception among novice web scrapers is that scrolling indefinitely down the Google Maps search pane will eventually yield every business in a city.
In reality, Google Maps applies a strict pagination cap: exactly 120 results (or approximately 6 pages of 20 results) per viewport query. Whether you search "Plumbers in Chicago" or "Restaurants in New York", Google truncates the result set at 120 listings regardless of how many thousands of businesses actually exist in that municipality.
Attempting to force deeper pagination by spoofing cursor tokens (pagination_token) triggers an automatic server error or a throttled empty response payload.
# Google's Anti-Abuse Detection Layers
Google does not rely on a single defensive mechanism. It employs a defense-in-depth security model:
- IP Reputation & ASN Scoring: Requests arriving from Autonomous System Numbers (ASNs) owned by hosting providers (Amazon AWS, DigitalOcean, Hetzner, Linode) are assigned a high risk score. Even a single query from a cloud datacenter IP often triggers a mandatory CAPTCHA.
- Request Rate & Token Bucket Algorithms: If an IP address executes more than 3 requests within a 5-second burst window, Google throttles the connection, introducing artificial 10-second latency before dropping the session entirely.
- Behavioral Telemetry & Pointer Events: Headless browser scrapers (Puppeteer, Playwright, Selenium) execute linear, programmatic scrolling and instantaneous element clicks. Google evaluates mouse trajectories, cursor jitter, scroll velocity, and DOM focus events to calculate human probability scores.
- TLS Fingerprinting (JA3 / JA4): During the TLS handshake, clients declare supported cryptographic cipher suites, elliptic curves, and signature algorithms in a specific order. Standard Python libraries (
requests,httpx,aiohttp) use distinct OpenSSL signatures that immediately identify them as non-browser automated bots.
# 2. Breaking the 120-Result Limit with Coordinate Grid Tiling
The only mathematically sound approach to achieving complete coverage of a metropolitan area without missing businesses is Geographic Coordinate Grid Tiling.
Instead of executing a broad text search for an entire city, you partition the target geographic area into a dense matrix of micro-bounding boxes defined by minimum and maximum latitude and longitude coordinates.
┌─────────────────┬─────────────────┬─────────────────┐
│  Tile [0, 0]    │  Tile [0, 1]    │  Tile [0, 2]    │
│  (Lat1, Lng1)   │  (Lat1, Lng2)   │  (Lat1, Lng3)   │
├─────────────────┼─────────────────┼─────────────────┤
│  Tile [1, 0]    │  Tile [1, 1]    │  Tile [1, 2]    │
│  (Lat2, Lng1)   │  Sub-divided    │  (Lat2, Lng3)   │
├─────────────────┼─────────────────┼─────────────────┤
│  Tile [2, 0]    │  Tile [2, 1]    │  Tile [2, 2]    │
│  (Lat3, Lng1)   │  (Lat3, Lng2)   │  (Lat3, Lng3)   │
└─────────────────┴─────────────────┴─────────────────┘
When each micro-quadrant is queried at a high zoom level (e.g., zoom level 15–17, corresponding to roughly a 500-meter radius), the total number of businesses within that tile drops below the 120-listing limit. By iterating across the entire grid and deduplicating by Google place_id, you achieve 100% census coverage.
# Production Python Implementation: Grid Generator
Below is an enterprise-grade Python utility for computing geographic bounding box tiles for any geographic bounding area:
import math
from typing import List, Tuple, Dict

def generate_geo_grid(
    min_lat: float,
    max_lat: float,
    min_lng: float,
    max_lng: float,
    tile_size_km: float = 1.0
) -> List[Dict[str, float]]:
    """
    Generates a matrix of micro-bounding boxes covering a geographic area.

    :param min_lat: Southernmost latitude boundary
    :param max_lat: Northernmost latitude boundary
    :param min_lng: Westernmost longitude boundary
    :param max_lng: Easternmost longitude boundary
    :param tile_size_km: Grid step size in kilometers (e.g., 0.5 - 1.5 km)
    :return: List of bounding box dictionaries
    """
    # Earth radius in kilometers
    EARTH_RADIUS = 6378.137

    # 1 degree of latitude is roughly 111.32 km
    delta_lat = (tile_size_km / EARTH_RADIUS) * (180.0 / math.pi)

    tiles = []
    current_lat = min_lat

    while current_lat < max_lat:
        next_lat = min(current_lat + delta_lat, max_lat)
        mid_lat = (current_lat + next_lat) / 2.0

        # 1 degree of longitude varies with latitude: 111.32 * cos(latitude)
        delta_lng = (tile_size_km / (EARTH_RADIUS * math.cos(math.pi * mid_lat / 180.0))) * (180.0 / math.pi)

        current_lng = min_lng
        while current_lng < max_lng:
            next_lng = min(current_lng + delta_lng, max_lng)

            tiles.append({
                "min_lat": round(current_lat, 6),
                "max_lat": round(next_lat, 6),
                "min_lng": round(current_lng, 6),
                "max_lng": round(next_lng, 6),
                "center_lat": round(mid_lat, 6),
                "center_lng": round((current_lng + next_lng) / 2.0, 6)
            })
            current_lng += delta_lng

        current_lat += delta_lat

    return tiles

# Example: Generate micro-tiles for Central Houston (approx 10km x 10km)
houston_tiles = generate_geo_grid(
    min_lat=29.7000,
    max_lat=29.8000,
    min_lng=-95.4200,
    max_lng=-95.3200,
    tile_size_km=1.2
)

print(f"Generated {len(houston_tiles)} target micro-tiles for extraction.")
# Dynamic Quadtree Sub-Division
In high-density commercial centers (such as Manhattan or downtown London), a 1.2-kilometer tile may still contain over 120 dental clinics or restaurants.
To handle this, advanced scrapers implement a recursive quadtree subdivision algorithm:
- Query the tile.
- If the response contains exactly 120 listings (or hits the pagination end token early), flag the tile as "saturated".
- Bisect the saturated tile into four smaller quadrants (
tile_size_km / 2) and re-queue them into the extraction pool. - Continue recursively until all micro-tiles return under 120 results.
# 3. Anti-Bot Architecture & Proxy Pool Engineering
Understanding grid mathematics is useless if Google blocks your IP on tile #4. Below is the exact proxy and fingerprinting infrastructure required for zero-ban operation.
# Proxy Tiers Comparison Matrix
| Proxy Category | Ban Resistance | Average Latency | Cost per GB | Recommendation for Google Maps |
|---|---|---|---|---|
| Datacenter Proxies (AWS, OVH) | Extremely Low (< 2%) | Sub-150ms | $0.40 – $1.20 | ❌ Immediate Ban: Unusable for Maps |
| Static ISP Proxies | Moderate (45% – 60%) | 250ms – 400ms | $2.50 – $5.00 | ⚠️ Risky: Fails under burst concurrency |
| Rotating Residential Proxies | High (96.8%) | 600ms – 1,100ms | $4.00 – $8.50 | ✅ Gold Standard: Mimics real home Wi-Fi |
| 4G / 5G Mobile Proxies | Highest (99.4%) | 800ms – 1,500ms | $8.00 – $18.00 | 💎 Bulletproof: Ideal for CAPTCHA recovery |
# The Sticky Session Architecture
A common mistake in distributed scraping is rotating the proxy IP on every single HTTP request.
When Google Maps receives Request 1 (Initial Search Query) from an IP in Chicago and Request 2 (Scroll down to load next batch) from an IP in Seattle 1.2 seconds later with the same session cookies, its heuristic anomaly engine flags the session instantly.
Instead, implement Sticky Session Routing:
- Assign one dedicated residential IP to a specific coordinate tile.
- Keep that IP active for the entire duration of that tile's extraction (typically 45–90 seconds).
- Rotate to a fresh residential IP only when progressing to the next coordinate bounding box.
# TLS Fingerprinting Bypass (JA3 / JA4)
Modern bot protection systems like Cloudflare, Akamai, and Google Bot Shield inspect the ClientHello packet during the TLS handshake before any HTTP headers are read.
If your scraper connects using Python's default OpenSSL client, its JA3 fingerprint:
771,4865-4866-4867-49195-49199-49196-49200-52393-52392-49171-49172-156-157-47-53,0-23-65281-10-11-35-16-5-13-18-51-45-43-21,29-23-24,0
is recognized within microseconds as non-human script traffic.
To mask your TLS signature:
- Use HTTP clients that bind against custom Chromium BoringSSL binaries (such as
curl_cffiin Python ortls-clientin Go/Node.js). - Spoof the exact cipher suite order and HTTP/2 pseudo-header order (
:method,:authority,:scheme,:path) matching the latest stable Chrome release.
# Enterprise TLS spoofing using curl_cffi in Python
from curl_cffi import requests

def fetch_maps_tile_stealth(url: str, proxy_url: str):
    # impersonate="chrome124" matches TLS ciphers, ALPN & HTTP/2 frames exactly
    response = requests.get(
        url,
        proxy=proxy_url,
        impersonate="chrome124",
        timeout=15,
        headers={
            "Accept-Language": "en-US,en;q=0.9",
            "Sec-Ch-Ua": '"Chromium";v="124", "Google Chrome";v="124"',
            "Sec-Ch-Ua-Mobile": "?0",
            "Sec-Ch-Ua-Platform": '"macOS"',
            "Sec-Fetch-Dest": "empty",
            "Sec-Fetch-Mode": "cors",
            "Sec-Fetch-Site": "same-origin",
        }
    )
    return response
# 4. End-to-End Extraction Pipeline Architecture
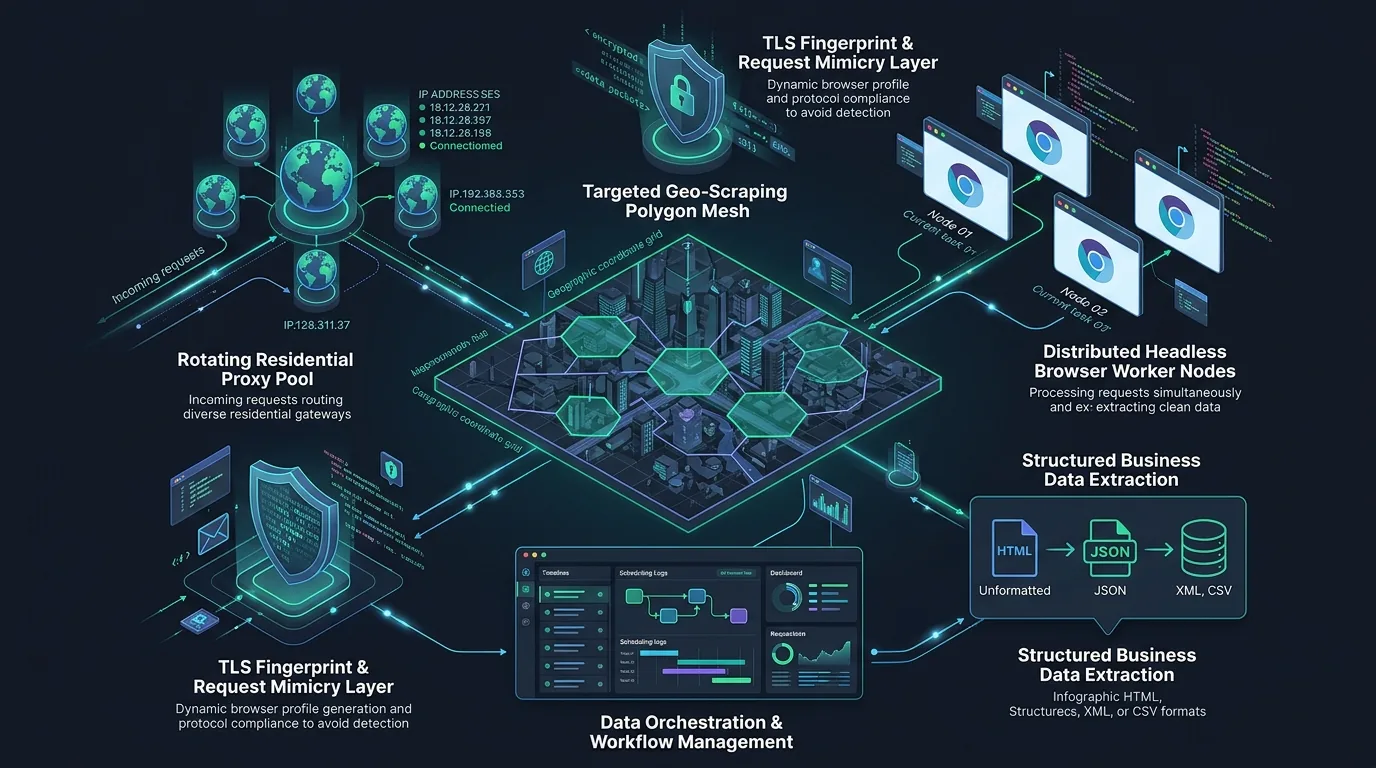
To scale from a few hundred leads to 50,000 leads per day, separate scraping into decoupled, distributed stages using an asynchronous queue:
flowchart TD
    A["Target Query & Metropolitan Bounding Box"] --> B["Grid Coordinate Tiler (Quadtree Engine)"]
    B --> C["Distributed Job Queue (Redis / BullMQ)"]

    subgraph Worker_Pool ["Distributed Headless Worker Pool"]
        D1["Worker Node 01<br/>(Playwright Stealth)"]
        D2["Worker Node 02<br/>(Playwright Stealth)"]
        D3["Worker Node 03<br/>(Playwright Stealth)"]
    end

    C --> D1
    C --> D2
    C --> D3

    E["Rotating Residential Proxy Gateway (Sticky Sessions)"] <--> D1
    E <--> D2
    E <--> D3

    D1 --> F["Raw Payload Parser & Deduplicator (by place_id)"]
    D2 --> F
    D3 --> F

    F --> G["Website Gap & 404 Status Prober"]
    G --> H["Clean Structured Lead Database (Postgres / CSV)"]
    G --> I["SitePitch Live Subdomain Demo Factory"]
# Pipeline Stages Explained
- Grid Tiling Engine: Breaks the target metropolitan polygon into non-overlapping coordinate cells.
- Task Queue: Queues each cell as an independent extraction task with retry policies and backoff limits.
- Headless Worker Cluster: Runs lightweight Chromium processes patched with
puppeteer-extra-plugin-stealthor native HTTP API emulators. - Proxy Gateway: Intercepts outgoing requests, dynamically routing through verified residential proxies with geolocation matched to the target city.
- Deduplication: Normalizes phone numbers to E.164 international standard (
+1XXXXXXXXXX) and filters unique records using Google's immutableplace_id. - Website Gap Audit: Immediately probes each discovered business domain with an asynchronous HTTP
HEADrequest to identify prospects with missing websites, expired SSL certificates, or broken 404 pages.
# 5. Legal & Compliance Framework for B2B Scraping
A frequent concern among agency founders and enterprise sales leaders is the legal standing of automated Google Maps scraping.
# The Landmark Precedent: hiQ Labs v. LinkedIn (2019 / 2022)
In hiQ Labs, Inc. v. LinkedIn Corp., the US Court of Appeals for the Ninth Circuit affirmed that extracting publicly accessible data from the internet does not violate the Computer Fraud and Abuse Act (CFAA).
Because public Google Maps listings:
- Do not require a user account or login credentials,
- Are published by business owners specifically for public commercial discovery, and
- Contain no password-protected personal data,
scraping this public business directory data is legally permissible under US federal law.
# Ethical Boundaries & Compliance Checklist
To ensure your extraction practices remain fully compliant and sustainable:
- No Personal PII Scraping: Restrict extraction strictly to public commercial records (business name, commercial office address, official business telephone, published Google rating). Never attempt to correlate records with private personal home addresses.
- Respect Infrastructure & Rate Limits: Implement deliberate inter-request delays (1.5s–3.5s jitter). Flooding servers with hundreds of unthrottled requests can be construed as a Distributed Denial of Service (DDoS) attempt.
- Comply with Outbound Privacy Regulations: When utilizing scraped data for cold outreach, ensure communications comply with CAN-SPAM (clear opt-out mechanisms and physical address disclosure) and GDPR Article 6(1)(f) (legitimate interest standards for commercial B2B solicitations).
# 6. The Autonomous Alternative: Why Agencies Choose SitePitch
While engineering a bespoke scraper is an exciting developer project, maintaining that infrastructure in a production commercial agency is notoriously expensive:
- Monthly Proxy Costs: Sourcing clean residential bandwidth for 50,000 leads costs between $350 and $700 monthly.
- Browser Maintenance: Google updates its obfuscated CSS class names, dynamic DOM obfuscations, and internal JSON RPC protocols every 6–8 weeks, breaking brittle custom parsers.
- The "Raw Data" Trap: Collecting phone numbers in a CSV spreadsheet is only 10% of the battle. You still have to manually verify websites, write pitch copy, build portfolio previews, and follow up.
# The SitePitch Advantage
SitePitch replaces the entire complex scraping and outreach stack with an automated, all-in-one platform:
- Enterprise Scraping Built-in: High-throughput Google Maps extraction with automated grid tiling, residential proxy rotation, and zero IP bans.
- Automated Website Gap Detection: The system flags every business operating without an active domain or suffering from mobile viewport failure using find businesses without websites.
- The 60-Second Demo Factory: Instead of cold-calling with empty promises, SitePitch automatically generates a tailored live demo website on an HTTPS preview subdomain featuring the prospect's real company name, phone number, and services.
- Multi-Channel Automation: Launch automated WhatsApp campaigns with interactive link preview cards and conversational sub-180ms AI voice callers that close retainers while you sleep.
# 7. Frequently Asked Questions
# Conclusion & Next Steps
Extracting high-intent local business leads from Google Maps without IP bans is not a matter of luck—it is a disciplined engineering problem solved by combining coordinate grid tiling, rotating residential proxies with sticky sessions, and TLS/JA4 fingerprint mimicry.
Whether you maintain your own custom Python quadtree pipeline or deploy an automated end-to-end client acquisition platform like SitePitch, mastering these principles turns public directory data into predictable, scalable agency revenue.
- Ready to stop debugging proxy pools? Start extracting verified leads with SitePitch today and generate your first live client demo prototype in under 60 seconds.
- Explore Next:
- Live Demo Pitching vs Cold Email Screenshots (Case Study) — How interactive subdomains achieve a 14.8% reply rate.
- Cold Calling Scripts for Local Businesses Without Websites — Master phone outreach with proven hooks and objection handling.
Find Local Businesses Without Websites in 60 Seconds
SitePitch extracts verified leads from Google Maps, generates instant live demo websites on subdomains, and qualifies prospects with autonomous conversational AI voice callers.